Today we build:
An
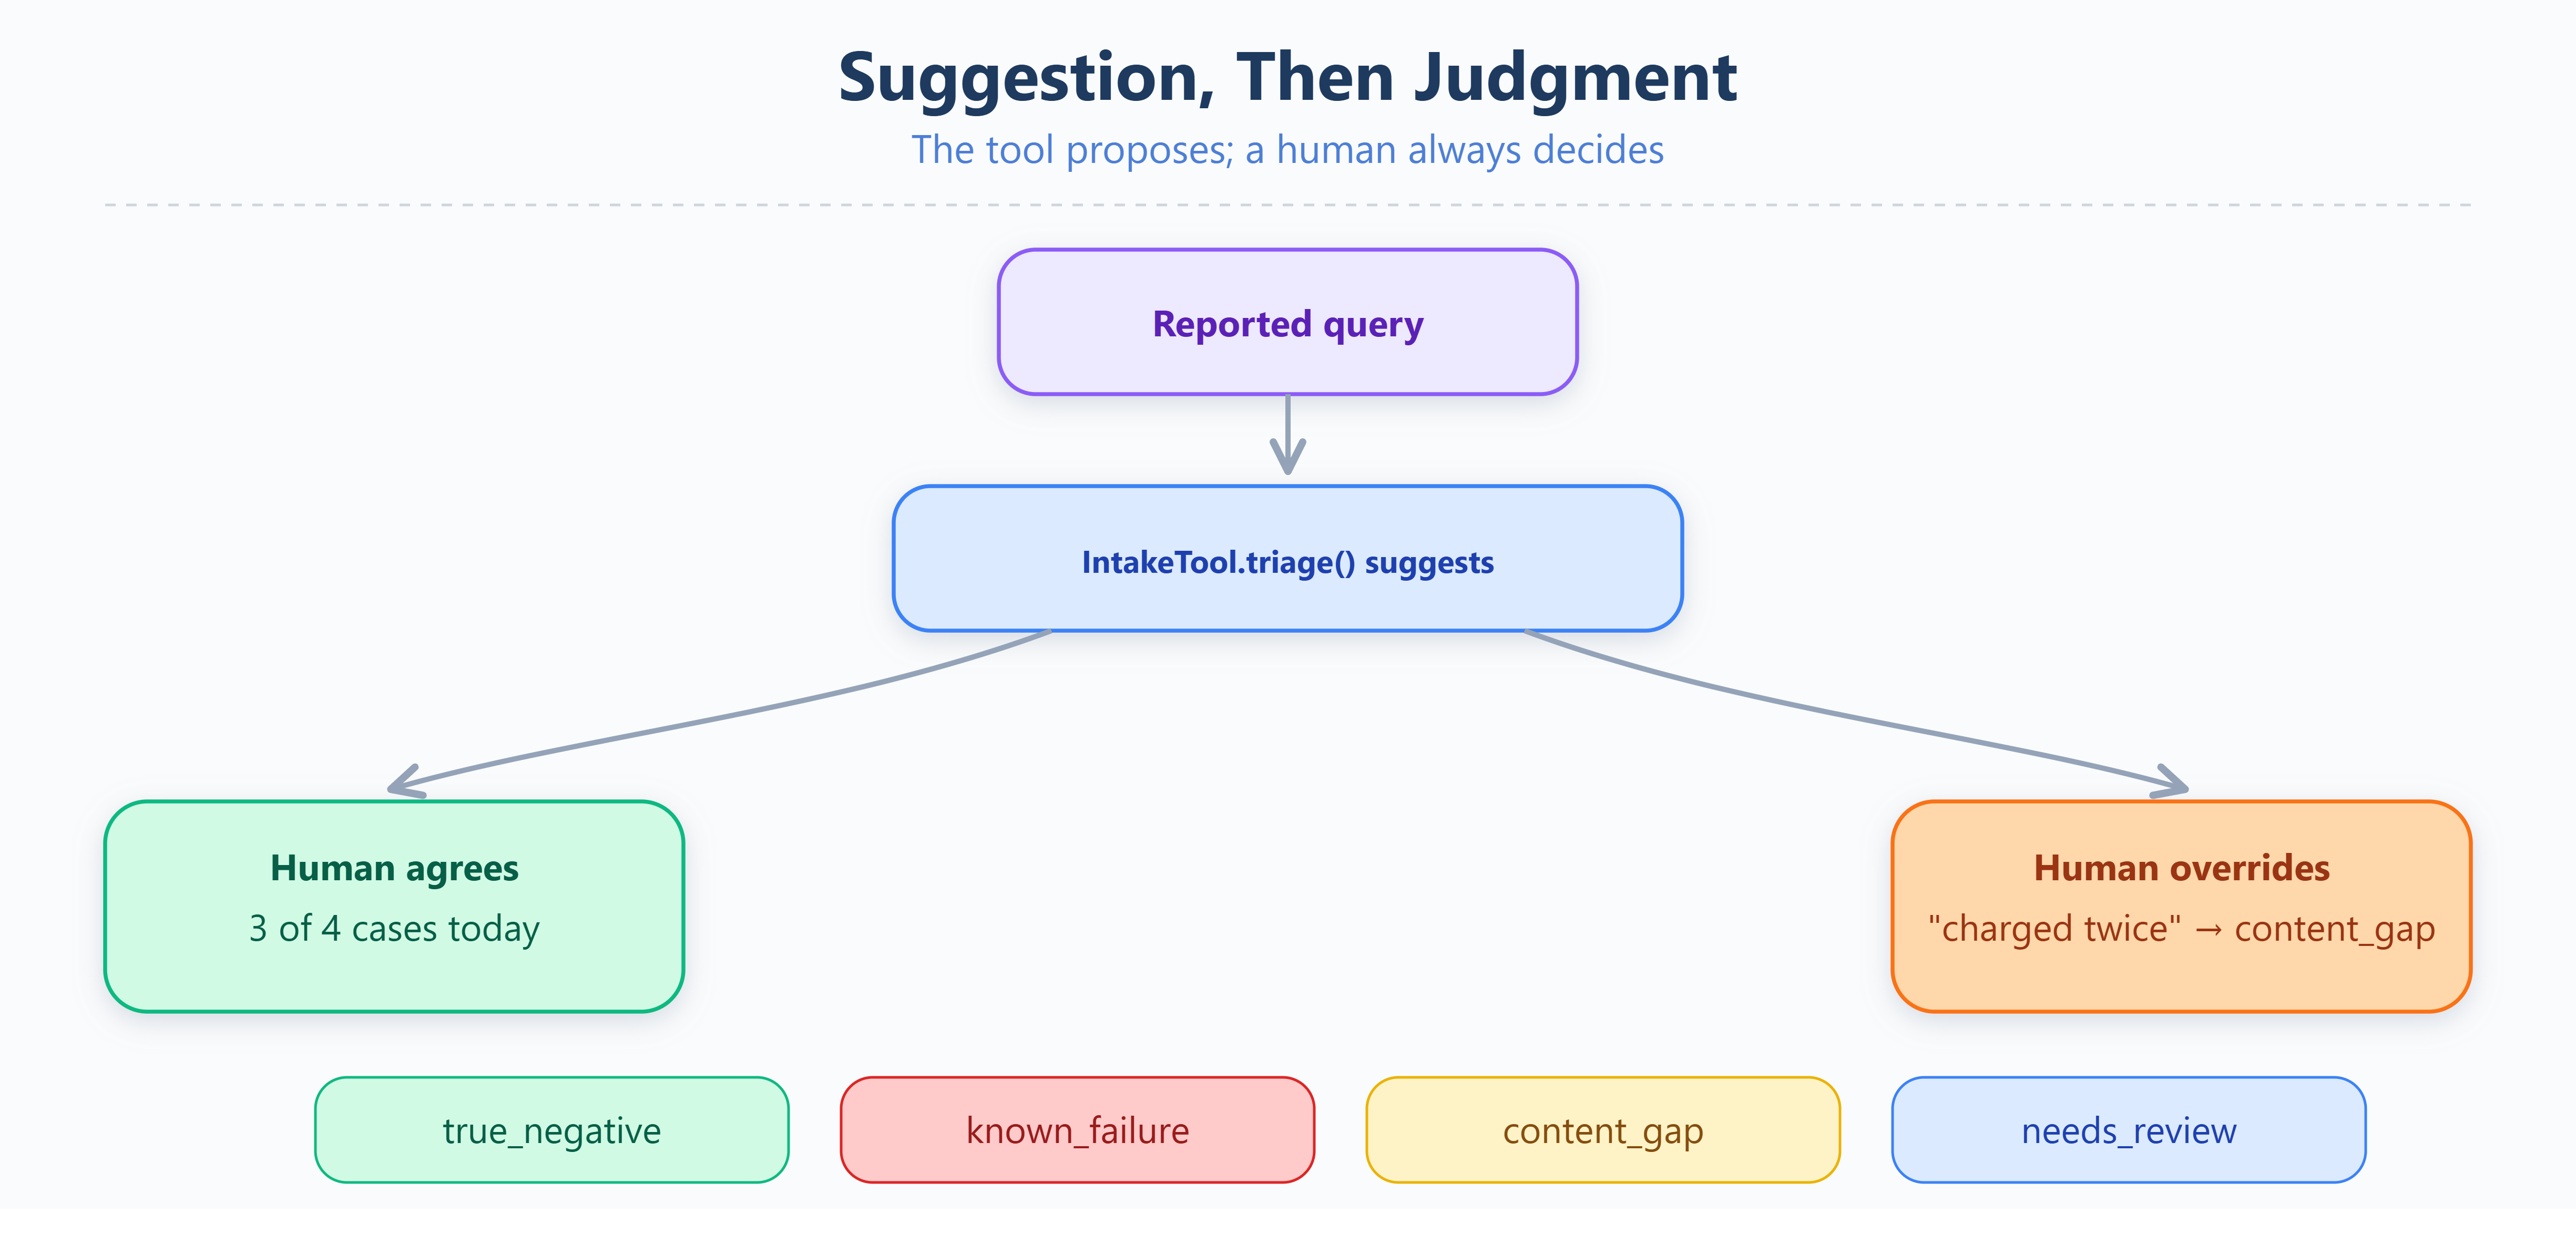
IntakeToolthat runs a reported query and suggests — never finalizes — a dispositionA four-way outcome: true negative, known failure, content gap, or needs review
One real human override of the tool’s own suggestion, proving judgment isn’t automated away
Why This Matters
Days 14 and 15 turned discovered failures into golden cases by hand — notice something odd, run it manually, inspect the trace, decide what “correct” means, write a
GoldenCase. That worked for fifteen cases built over two lessons. It doesn’t scale to the volume a real system generates once real users start reporting real problems, and it depends entirely on someone remembering to follow the same steps every time. Today formalizes the steps — without pretending a tool can make the judgment call a human still has to make.
Core Concept
IntakeTool.triage()runs a reported query through the pipeline and applies one honest heuristic: an out-of-scope query with no extracted entity suggests a genuine negative — nothing about the query pointed toward any covered topic. An out-of-scope query that did extract an entity (like “annual” from “Can I switch from monthly to annual?”) gets flaggedneeds_reviewinstead, because entity extraction succeeding while intent classification fails is itself a signal worth a second look. Any in-scope query always getsneeds_review— the tool has no way to verify retrieved content is actually correct without a human reading it.The heuristic is deliberately narrow, and
finalize_review()never trusts it blindly — every reviewed case requires an explicit disposition and notes from a human. One of today’s four reviews shows this directly: the tool suggestedtrue_negativefor “My card was charged twice, can you help?”, reasoning that no entity was extracted. The human reviewer overrode it tocontent_gap— billing disputes are plausibly in scope, just not covered by any current passage, and routing them intorefund_policytoday would trigger the exact retrieval-precision bugs Days 12 and 15 already documented. The tool’s suggestion was reasonable; it also wasn’t the full picture, which is exactly why it’s a suggestion and not a verdict.Not every reviewed query becomes an eval case. Two of today’s four — the plan-switching and billing-dispute queries — are logged as content gaps instead: real, valid questions the system genuinely can’t answer yet, where the fix is new passages, not a code change or a pass/fail test. Turning those into eval cases today would just create tests designed to fail forever, which teaches a dataset nothing useful.
Architecture
IntakeReport carries the full PipelineTrace alongside the tool’s suggestion and reasoning. finalize_review() takes that report plus a human’s final_disposition and reviewer_notes, and only constructs a GoldenCase when the disposition is true_negative or known_failure — content_gap and unresolved needs_review cases produce no case at all, by design.